Datachain

DataChain Blog

Find here DataChain news, findings, interesting reads, community takeaways, deep dive into machine learning workflows from data versioning and processing to model productionization.

Insights

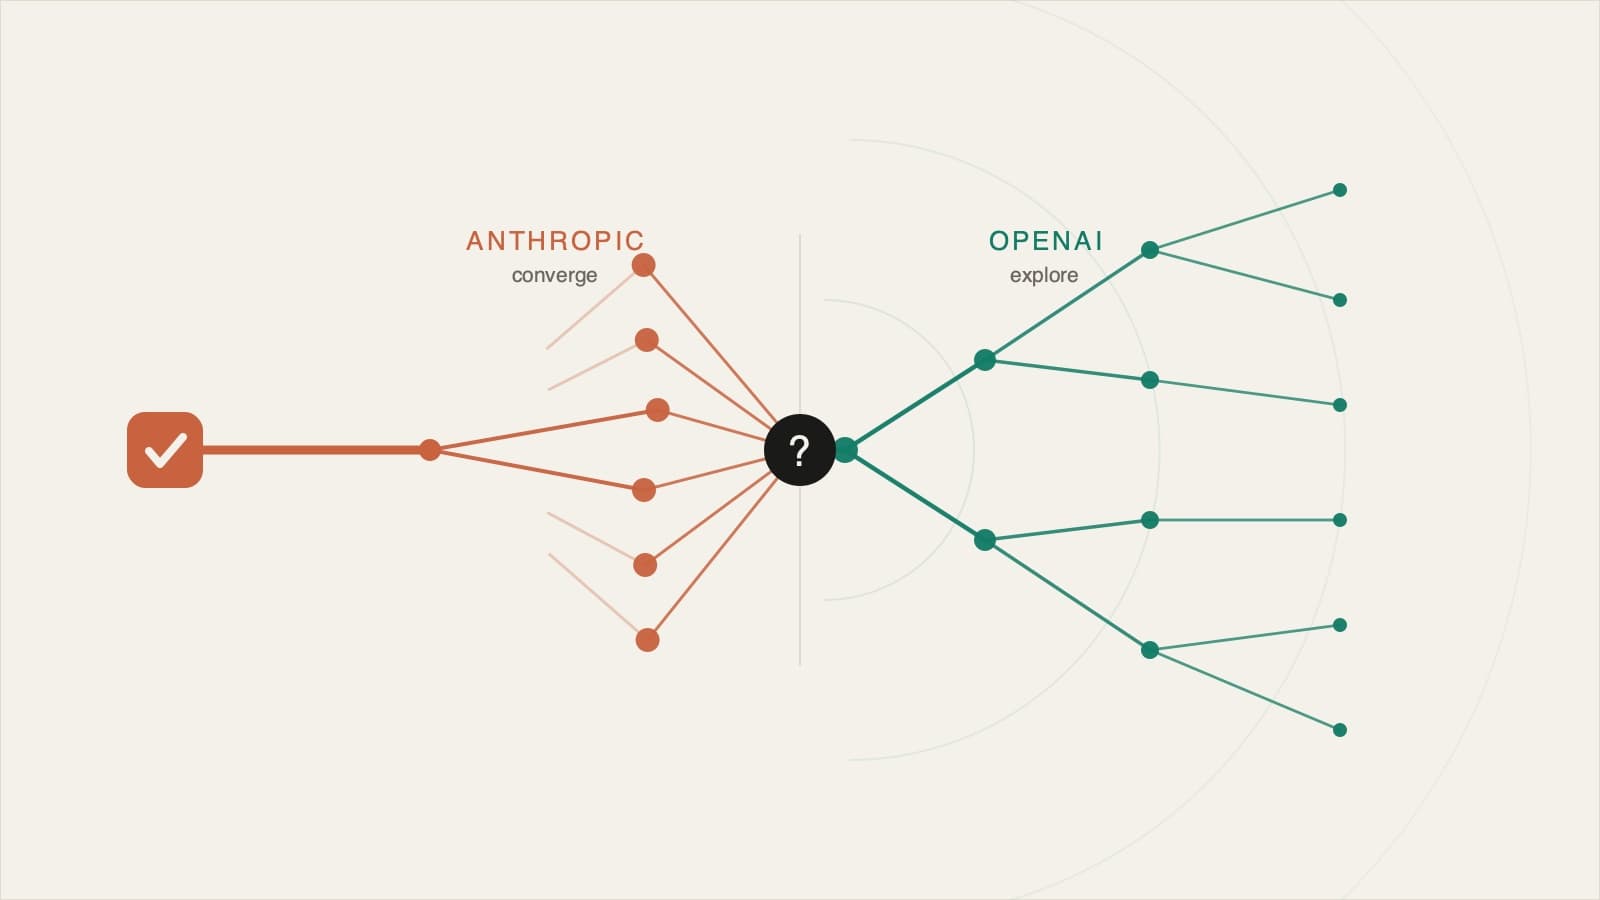
We read OpenAI's and Anthropic's data-agent posts so you don't have to

In January OpenAI published how it built an internal data agent. Last week Anthropic published how it built one too. Two frontier labs, the same problem, five months apart. Here is the honest side-by-side: what they agree on, where they diverge, and the one assumption they both quietly depend on.

Dmitry Petrov
Product

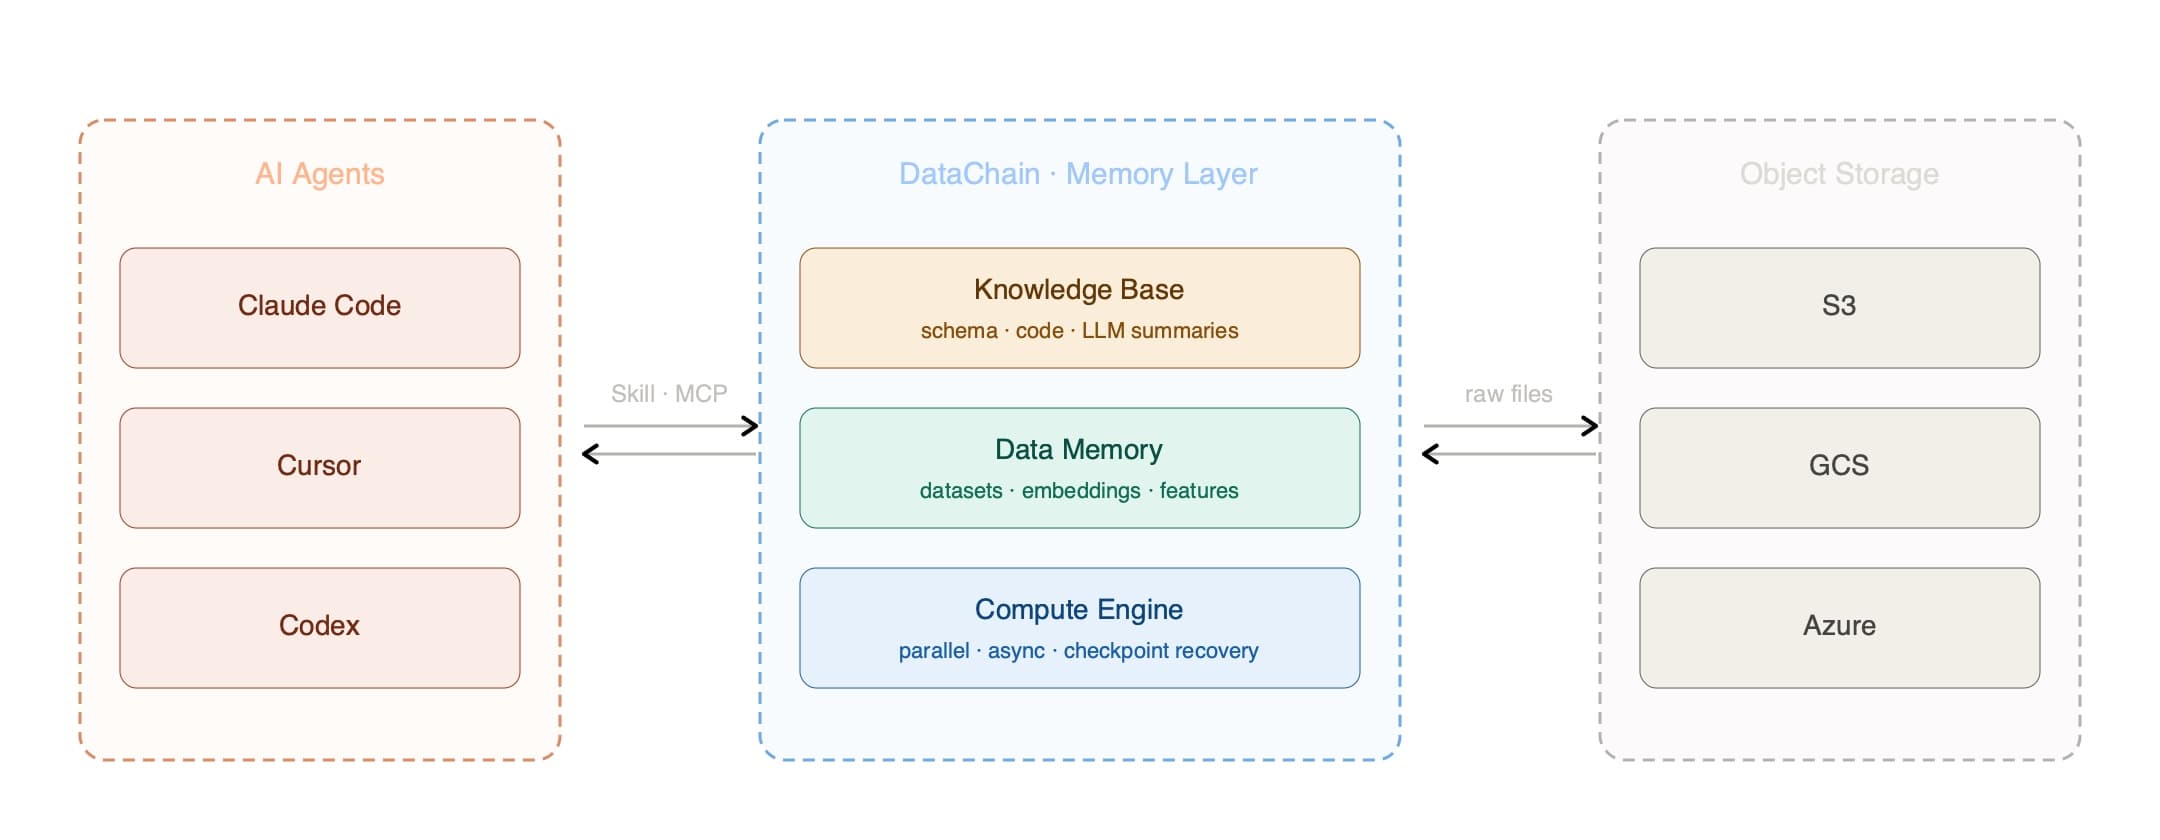
OpenAI's Data Agent and the S3 Gap

OpenAI built their in-house data agent for structured warehouse data, where schema, lineage, and queries come for free. Files in S3, GCS, or Azure - videos, sensor logs, image corpora, PDFs - have none of that, and the problems get a lot more interesting. Here is how we built the four foundations that close the gap.

Dmitry Petrov

Insights

From Big Data to Heavy Data: Rethinking the AI Stack

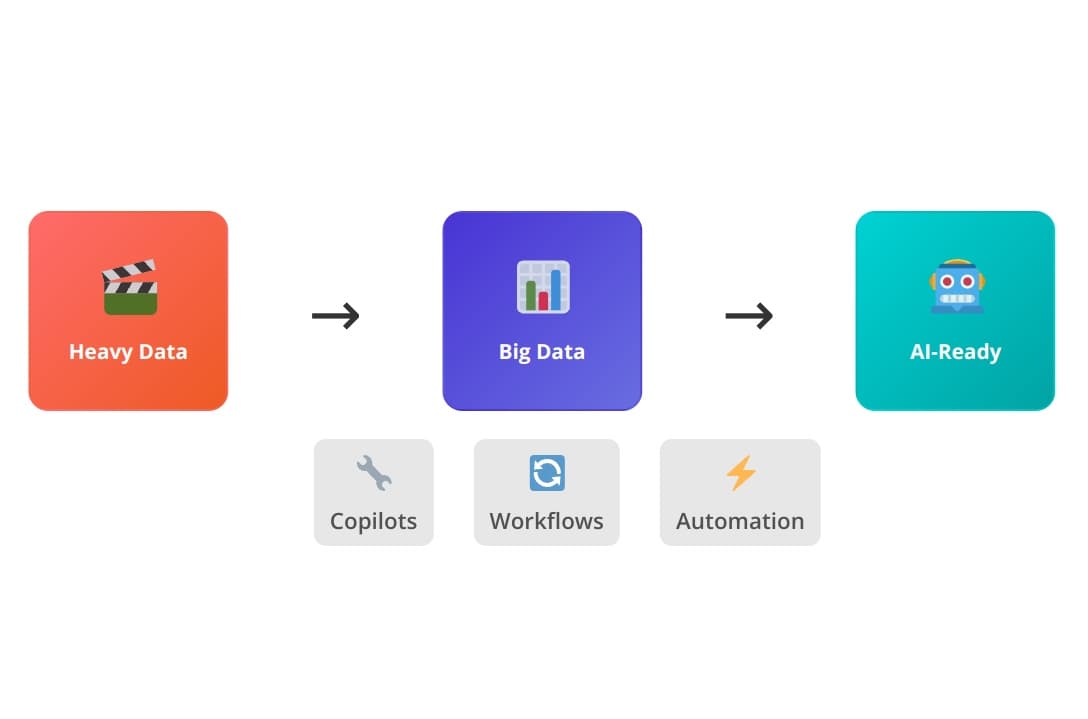
LLMs can finally interpret unstructured video, audio, and documents — but they can't do it alone. This post introduces the concept of heavy data and explores how modern teams build multimodal pipelines to turn it into AI-ready data.

Dmitry Petrov

Add the missing data context layer to your object storage

Book a Demo